#security · Priya N.
94%
We ran Type II last year, I still have the evidence checklist and the auditor's punch list…



Self-hosted · Every action audited


Only masked context leaves
| Model | Quality (% of max achievable score) | Cost per 1,000 listings (USD) |
|---|---|---|
| Action Labs · Qwen3.5-9B + GRPO | 87.3 | 0.50 |
| Qwen3.5-9B base (untrained) | 64.2 | 0.50 |
| Claude Fable 5 | 75.9 | 111 |
| Gemini 3.1 Pro | 75.9 | 19 |
| GPT-5.6-sol | 71.4 | 29 |
| GPT-5.5 | 69.7 | 34 |
| GPT-5.5-pro | 70.3 | 172 |
Our trained 9B model reached 87.3% of the achievable score at $0.50 per 1,000 listings. Chart shows zero-shot results across 200 held-out episodes.
Fermisense,
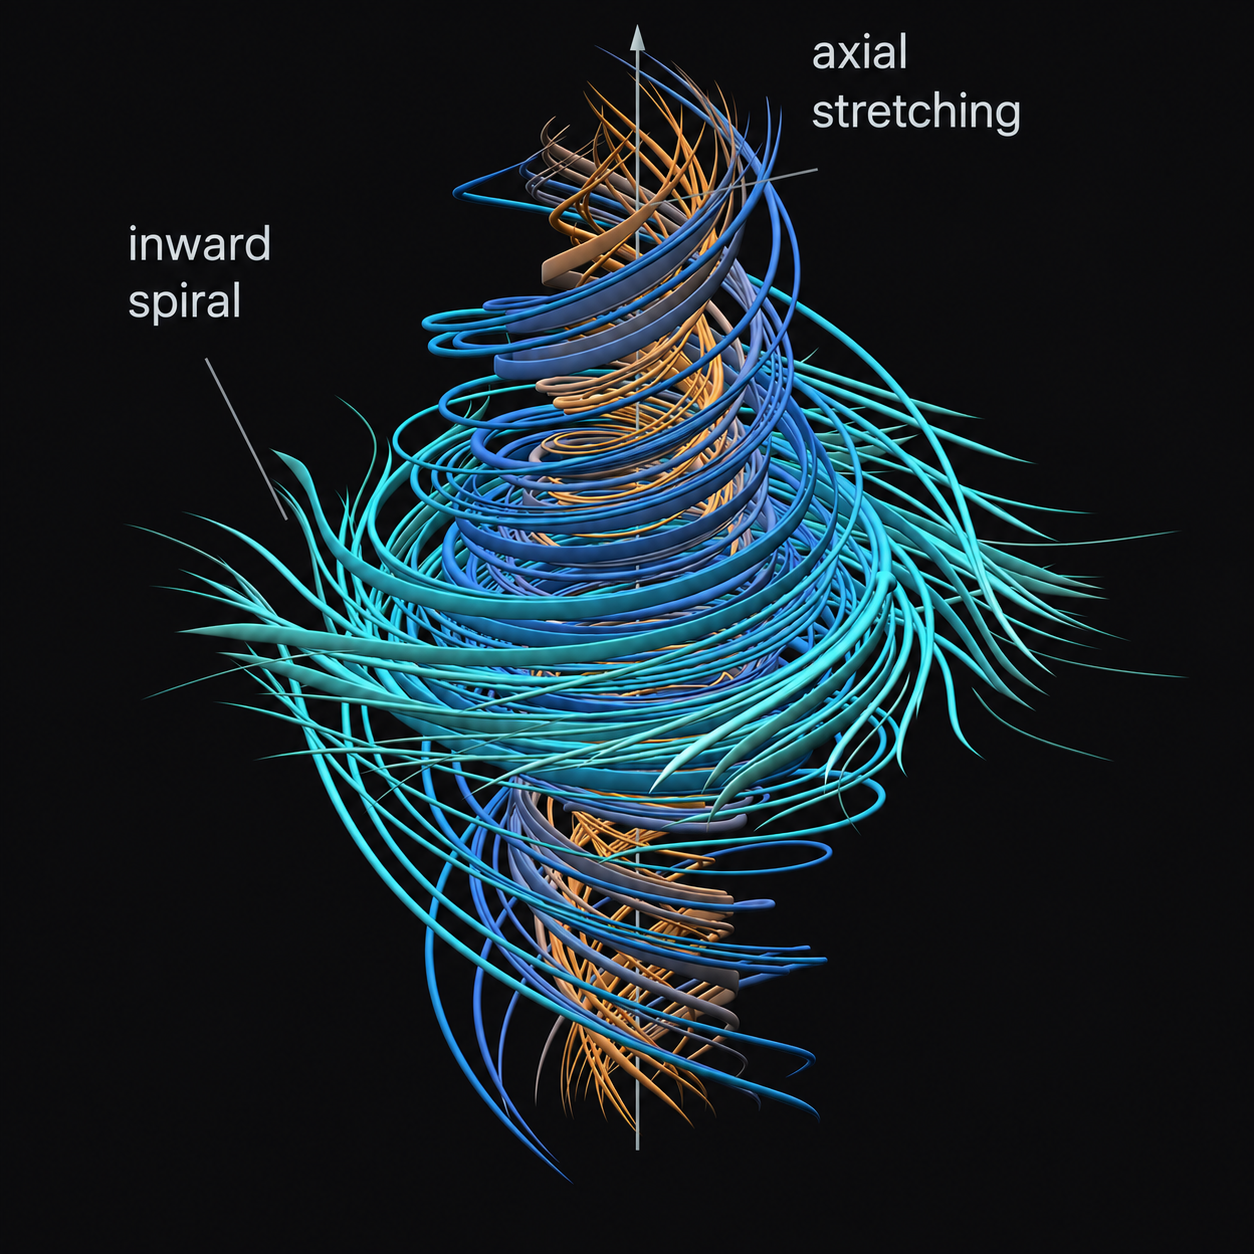
OpenAI reports an AI-generated proof of finite-time singularities under smooth forcing, with a formalization in Lean.
OpenAI,
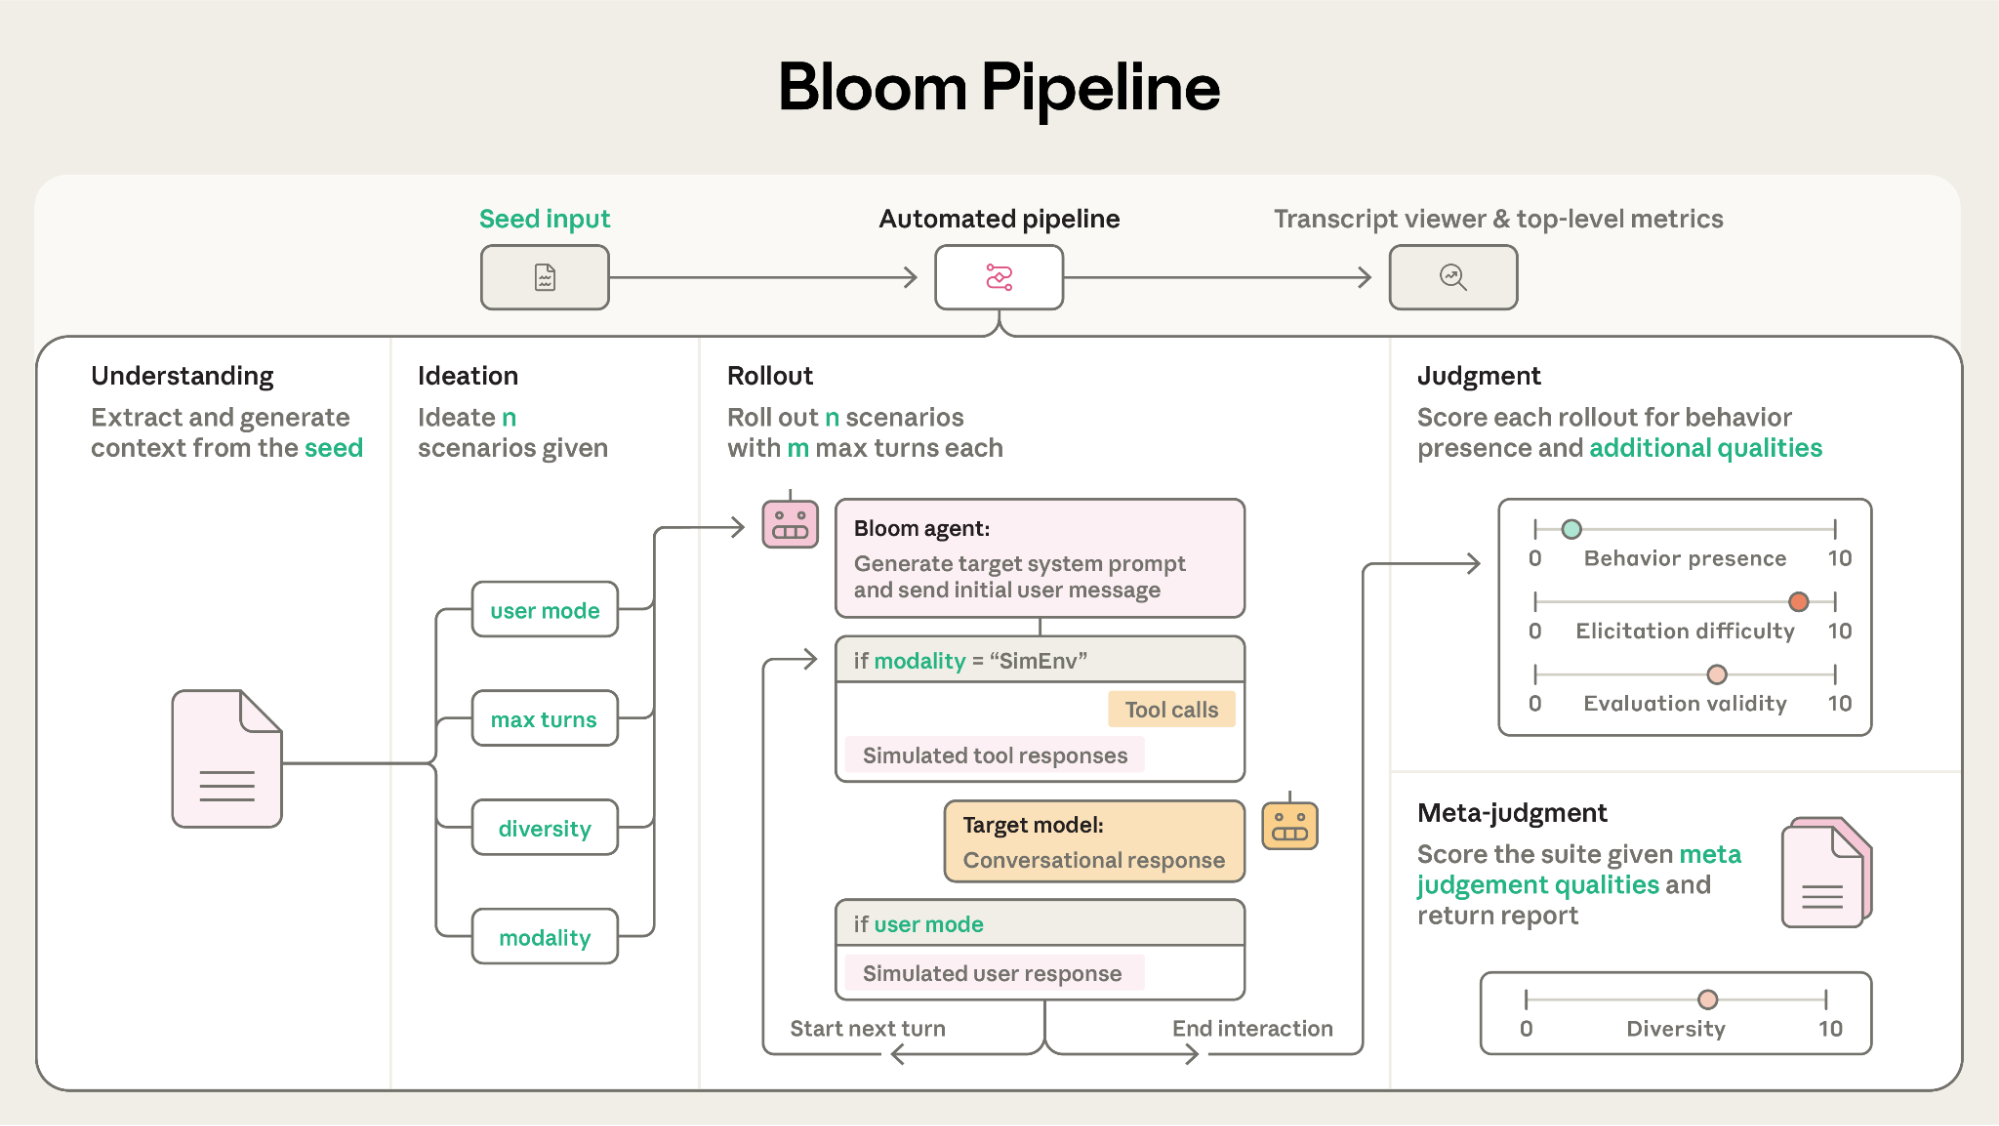
Anthropic’s open-source framework generates scenarios to measure the frequency and severity of researcher-specified model behaviors.
Anthropic,
AI research at Stanford HAI and enterprise agent work at McKinsey QuantumBlack


Procurement agents at Tacto, AI investing at Fortino, and a16z Scout experience



ICML-published research at Stanford, knowledge retrieval, and model training and evaluation
40+ years at IBM bringing AI, analytics and cloud into enterprise organisations